Baccarat Hypothesis Testing Checklist: A Research-Quality Workflow
The spreadsheet is still glowing on my monitor long after the evening games have ended. Thousands of baccarat results fill the rows, and one highlighted Banker streak has prompted a dramatic claim: the shoe must be biased. In review work like this, the pattern is worth examining, but it is not yet evidence. Before calculating anything, I need to know how the hands were collected, what claim was defined in advance, and whether the analysis quietly changed after someone noticed the streak.
That distinction is the purpose of this Baccarat Hypothesis Testing Checklist. It is a research workflow for evaluating claims about Banker, Player, and Tie outcomes, card sequences, shuffle integrity, simulated games, player behavior, or random number generator output. It is not a method for predicting the next hand, defeating the house edge, or recovering losses.
What Hypothesis Testing Can Actually Establish
A hypothesis test asks whether observed data are reasonably compatible with a specified model. The null hypothesis usually represents the benchmark—for example, that outcome frequencies follow predefined probabilities—while the alternative describes a departure that the study is designed to detect.
The result is conditional. It depends on the model, data quality, sampling method, test choice, and assumptions. A small p-value indicates that a result at least as extreme as the observed one would be unusual if the null hypothesis and its assumptions were true. As the NIST explanation of p-values makes clear, it is not the probability that the null hypothesis is false.
A test can identify a deviation that deserves investigation. It cannot, by itself, prove cheating, certify a game as permanently fair, or guarantee what will happen next. Statistical significance also says nothing automatically about practical importance: a tiny difference may become statistically detectable in a huge file while remaining operationally trivial.
The Baccarat Hypothesis Testing Checklist
I use the following sequence to keep an interesting pattern from becoming an overconfident conclusion. Each item includes a self-diagnostic question that can be answered before publication.
1. Define one precise research question
Replace a broad suspicion such as “the game looks wrong” with a measurable question. Examples include whether the three outcome frequencies differ from a predefined distribution, whether Banker-to-Banker transitions occur more often than the model predicts, or whether shuffled card positions show unexpected dependence.
Keep outcome questions separate from behavior questions. “Did Banker occur unusually often?” concerns game results. “Did players increase stakes after Banker wins?” concerns decisions. Those questions require different variables, assumptions, and tests.
Self-diagnostic: Could another researcher identify exactly what is being tested without asking what “suspicious” means?
2. Write the null and alternative hypotheses
State both hypotheses before inspecting the result. For a three-category frequency test, the null might say that Banker, Player, and Tie proportions equal a predefined theoretical or specification-based distribution. The alternative might say that at least one proportion differs.
Use a one-sided alternative only when direction was justified in advance. If either an excess or shortage would matter, a two-sided test is normally the honest choice. Selecting a direction after seeing the data understates uncertainty.
Self-diagnostic: Were the hypotheses written before the most interesting pattern was selected?
3. Define every variable and expected distribution
Document how Banker, Player, Tie, void rounds, incomplete rounds, duplicate records, and correction events are coded. For card-level research, define rank, position, deck or shoe identifier, cut point, and reshuffle boundary. For RNG work, distinguish raw generator output from values that have been scaled, mapped to cards, shuffled, or processed by game rules.
Expected probabilities must match the actual game configuration and research question. Rules, deck count, drawing logic, and treatment of ties can affect the benchmark. Do not substitute a remembered headline probability for a model defined for the game being studied.
Self-diagnostic: Could every row be classified consistently using a written data dictionary?
4. Validate the data source
Record the source, collection period, time zone, game version, table or software identifier, and extraction method where available. Check for missing hands, duplicated rows, impossible timestamps, format changes, selective recording, and interrupted shoes. A clean-looking file can still be a biased sample if it contains only memorable sessions or reported streaks.
Document every exclusion and its reason. If cleaning decisions change after results are calculated, preserve both the original and revised analyses.
Self-diagnostic: Can I explain where the data came from and account for every removed observation?
5. Examine independence and clustering
Many textbook tests assume independent observations. Baccarat records may be clustered by shoe, table, dealer, software version, session, player, or collection device. Card outcomes within a finite shoe also arise from a changing composition, so treating every hand as identically distributed and independent may be inappropriate for some questions.
The solution may involve analyzing at shoe level, modeling clusters, testing transitions, or using a simulation that reproduces the dealing process. Independence should be investigated, not assumed merely because each hand occupies a separate row.
Self-diagnostic: What shared process could connect neighboring records, and has the analysis accounted for it?
6. Plan sample size and statistical power
There is no universal number of baccarat hands that makes a test adequate. Required sample size depends on the significance level, desired power, variability, number of categories, model, and smallest meaningful effect. A thousand hands might detect a large discrepancy but miss a subtle one; it cannot be labeled sufficient without defining the target effect.
Plan the sample before testing whenever possible. If the sample is fixed, report what effect sizes it could plausibly detect instead of presenting the available number as automatically adequate.
Self-diagnostic: Have I specified the minimum difference that matters and assessed whether the study could detect it?
7. Set alpha and the analysis plan in advance
Alpha is the threshold used to decide when evidence is sufficiently incompatible with the null hypothesis for rejection. Choose it before viewing the outcome, and preregister the primary variables, exclusions, test, direction, sample endpoint, and treatment of missing data when the project permits.
Repeatedly testing every table, window, streak length, and outcome creates opportunities for false alarms. Correct for multiple comparisons, label exploratory work honestly, and confirm discoveries on new data.
Self-diagnostic: How many analytical choices or tests were attempted before the reported result appeared?
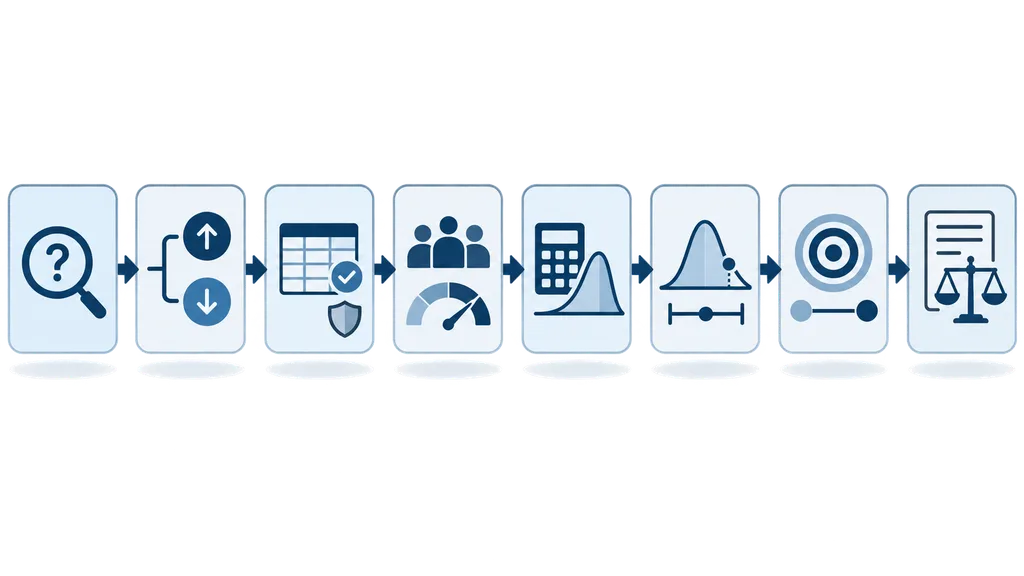
8. Select a test that matches the claim
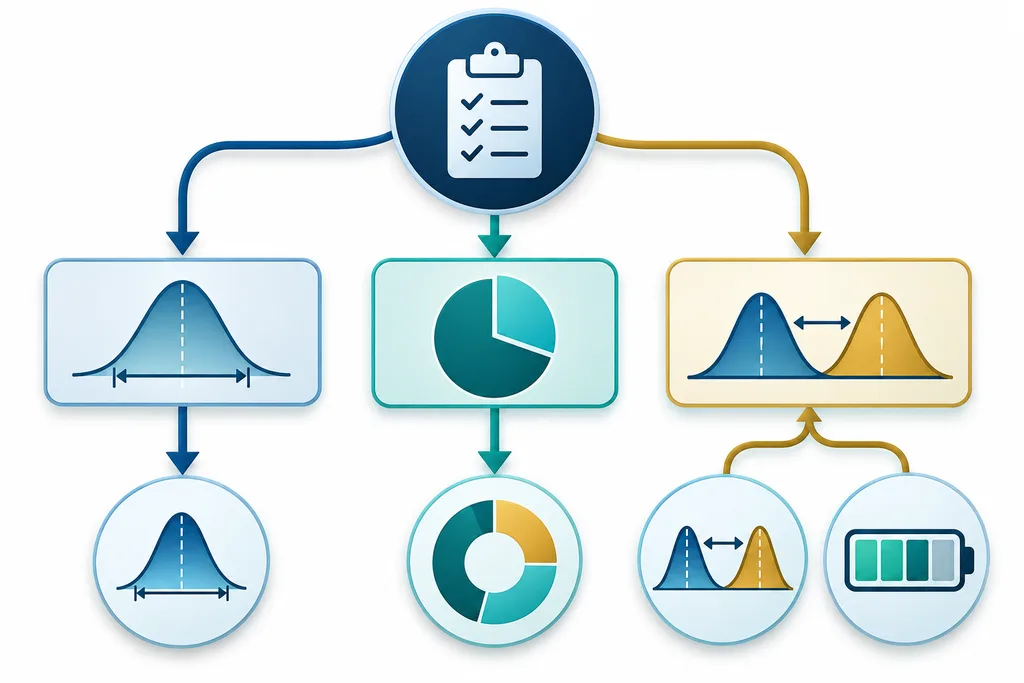
A chi-square goodness-of-fit test may suit a comparison of observed Banker, Player, and Tie counts against fully specified expected proportions, provided expected counts and assumptions are appropriate. A binomial or proportion test may fit a predefined two-category question. Runs, transition, serial-correlation, or permutation procedures can address sequence behavior, but each targets a different property.
Simulation or resampling is often helpful when dealing rules, finite-shoe structure, rare ties, small expected counts, or complex dependence make a simple approximation questionable. The simulation must reproduce the null process faithfully; otherwise, precision in the output disguises weakness in the model.
Self-diagnostic: Does the chosen test answer the original question under assumptions that the data reasonably satisfy?
9. Report p-values, confidence intervals, and effect sizes
Never allow a p-value to carry the entire conclusion. Report the observed and expected values, test statistic, degrees of freedom where relevant, exact or appropriately rounded p-value, and an effect-size measure. Add confidence intervals for proportions, differences, or other key estimates.
For corresponding procedures, confidence intervals and hypothesis tests express related information: a hypothesized value outside the relevant interval is associated with rejection at the matching significance level. More importantly, the interval shows the range of effect sizes that remain compatible with the data.
Self-diagnostic: Can the reader judge the size and uncertainty of the deviation, not merely whether p crossed a threshold?
10. Interpret the result without overclaiming
“Fail to reject” does not mean “prove fair.” It may reflect compatibility with the model, inadequate power, noisy data, or an insensitive test. Likewise, rejection does not prove fraud. Possible explanations include collection errors, model misspecification, dependence, undisclosed rule differences, repeated testing, software implementation problems, or a genuine deviation requiring controlled follow-up.
A passing randomness test covers only the property and sample examined. Formal RNG evaluation can also require documentation review, source-code examination, raw-output testing, and checks of scaling, shuffling, mapping, and final game behavior. The UK Gambling Commission testing procedure illustrates this layered approach for its jurisdiction; it should not be treated as universal global law.
Self-diagnostic: Have I listed credible alternative explanations and stated what additional evidence would distinguish among them?
A Compact Review Table
| Checklist item | What to verify | Question to ask |
|---|---|---|
| Claim | Specific outcome, sequence, or behavior | Was it defined before inspection? |
| Model | Rules and expected distribution | Does it match this game? |
| Data | Source, completeness, and exclusions | Could selection change the result? |
| Dependence | Shoes, sessions, tables, and versions | Are rows truly independent? |
| Design | Power, alpha, and multiple testing | Was the plan fixed in advance? |
| Reporting | Effect size, interval, and limitations | Is practical importance visible? |
A Short Banker, Player, and Tie Example
Suppose a researcher wants to determine whether outcome frequencies depart from a predefined distribution. No real audit data are needed to describe the plan. First, specify the applicable game rules and expected Banker, Player, and Tie probabilities. Then define the null as equality with those probabilities and the alternative as a difference in at least one category.
Next, choose a collection period and sample endpoint, validate complete records, decide how void rounds are handled, and examine clustering by shoe. Plan an appropriate goodness-of-fit procedure or a rule-faithful simulation, set alpha, define any follow-up comparisons, and assess power for a meaningful deviation.
After the sample closes, report category counts and proportions, expected counts, the test result, effect size, and uncertainty intervals. If the overall test rejects the null, investigate which categories contributed while accounting for follow-up comparisons. The conclusion should say that the observations were inconsistent with the specified model under stated assumptions—not that cheating was proven.
Frequently Asked Questions
Does a small p-value prove cheating?
No. It indicates that the observed result would be unusual under the null model, assuming the test and data are valid. Data errors, dependence, rule mismatches, multiple testing, or implementation issues may also produce a significant result.
Are 1,000 hands enough?
Not as a universal rule. Adequacy depends on the effect you want to detect, desired power, alpha, outcome variability, test design, and dependence structure. State those inputs before deciding whether any sample is sufficient.
Does every streak require a statistical test?
No. A streak can simply be described. Test it only when there is a meaningful predefined claim about run length, transition frequency, or independence. Searching many possible streak definitions after the fact demands multiple-testing controls and independent confirmation.
Does passing a randomness test prove a game is fair?
No. It means the examined sample was compatible with the tested property and model. Fairness is broader and may involve implementation, mapping, rules, security, controls, and independent technical review.
Final Self-Diagnostic Before Publishing
- Did I define the claim, hypotheses, expected distribution, alpha, and stopping rule before examining the decisive result?
- Did I document the source, missing records, exclusions, duplicates, rule version, and shoe or session boundaries?
- Did I justify independence assumptions, sample size, power, test selection, and multiple-comparison handling?
- Did I report effect sizes and confidence intervals alongside p-values?
- Did I distinguish exploratory findings from confirmatory tests?
- Did I avoid claims about prediction, guaranteed profit, fraud, or permanent fairness?
- Could another researcher reproduce the workflow and understand its limitations?
Disciplined Uncertainty Beats a Dramatic Pattern
When I return to that highlighted Banker streak, the rows look no less interesting than they did at the beginning. What has changed is the quality of the question. The Baccarat Hypothesis Testing Checklist turns visual surprise into a documented process: define the claim, protect the data, choose the model, quantify uncertainty, and resist conclusions the evidence cannot carry.
A streak may lead to a worthwhile investigation, and a significant deviation may justify controlled follow-up. Neither supplies tomorrow’s result or a ready-made accusation. In baccarat research, disciplined uncertainty is not a weakness. It is what keeps an arresting pattern from being mistaken for knowledge—and what makes genuine evidence easier to recognize when it finally appears.